Turn any spreadsheet into real answers, automatically.
Upload a CSV. Auto Data Analyst cleans it, explores it, trains and compares a dozen+ machine learning models — including XGBoost, LightGBM, and CatBoost — and hands you concrete recommendations. Every step is visible and editable, and your data never leaves your computer.
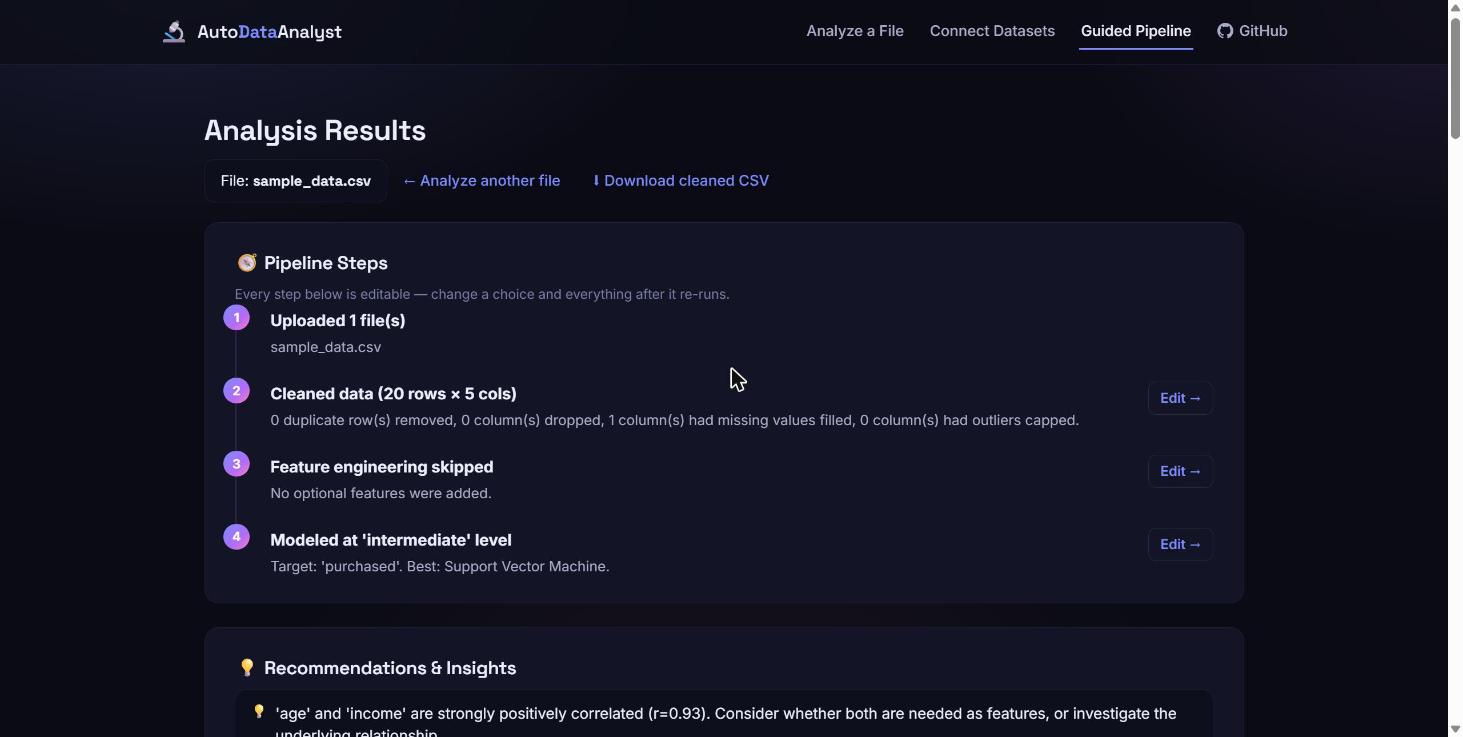
How it works
Four steps, fully automatic by default — or take the wheel at any point.
Upload
Drop in a CSV, or several related ones — the app finds the join columns for you.
Clean & engineer
Missing values, outliers, encoding, and optional derived features — see the plan, edit any of it.
Compare models
Runs classification, regression, or clustering across a wide model pool and ensembles the best.
Get answers
Plain-language recommendations, plus a chat box to ask your own questions about the results.
Why not just use a black-box AutoML tool?
Most AutoML platforms trade transparency and privacy for convenience. This doesn't.
Nothing is a black box
Every cleaning decision, every model tried, every threshold chosen is shown to you — not just a final score.
Your data stays yours
Everything runs locally. No upload to a third-party cloud, no API calls with your rows in them.
A real model bake-off
Not one model's guess — a dozen+ candidates including XGBoost, LightGBM, and CatBoost, cross-validated and ensembled.
Free, open source
No subscription, no per-row pricing. Flask + scikit-learn, the code is yours to read on GitHub.